Creator
$19/month
Billed monthly
For solo creators posting every week
500 credits every month
- Up to 500 Image-01 images
- Up to 41 H3 Max clips
- Up to 1.5 hours of AI voiceover
- Roll over up to 1,000 credits
Video and image models from
MiniMax is a Shanghai AI company with models for text, code, video, speech, music, and images. Sceneform is a separate studio that runs its video and image models on one plan.
Plans from $19 a month. Commercial use on every paid plan.
Looking for MiniMax itself? MiniMax Agent · API platform · minimax.io
VideoH3 Max
ImageImage-01
MiniMax builds its own models for text, code, video, speech, music, and images, and sells them through its own apps and an API at minimax.io. Sceneform runs seven of its models: five for video, one for images, and one for speech that new accounts can only listen to.
Video
The Hailuo and H3 video models
Runs here: H3 Max, H3 Max Turbo, Hailuo 03, Hailuo 2.3, Hailuo 2.3 Fast
See the video modelsSpeech
MiniMax Speech, text to speech
Runs here: Speech 2.8 HD. New accounts can listen, not run it: it needs a MiniMax voice, and Sceneform offers none.
Hear itImage
Image-01
Runs here: Image-01
See its draftsMusic
MiniMax Music
Not here. Music in Sceneform runs on other models.
AI music generatorText and code
The M series of language and coding models
Not here. MiniMax Agent, MiniMax Code, and the M models are at minimax.io.
Apps and API
Hailuo AI, MiniMax Audio, MiniMax Code, and an API platform
Not needed here. MiniMax's apps and API are at minimax.io. Sceneform is a separate studio, so it needs no MiniMax account or API key.
MiniMax calls its video models Hailuo and H3. All five run here, from a prompt or from a first frame.
The sharpest picture, with sound every time
SoundAlways
Sharpest2K
Length5 to 15 s
Starts fromA prompt, a first and last frame, or up to 9 images, 3 clips, and 3 sounds
Clips that follow your own images, clips, or sounds
SoundYes
Sharpest768p
Length5 to 15 s
Starts fromA prompt, a first and last frame, or up to 12 images, clips, and sounds
H3 clips with sound at half the price of H3 Max
SoundYes
Sharpest768p
Length5 to 15 s
Starts fromA prompt, or a first and last frame
Silent clips in 1080p, from a prompt or a photo
SoundSilent
Sharpest1080p
Length6 or 10 s, 6 s at 1080p
Starts fromA prompt, or a first frame
Silent clips from a photo, for less than Hailuo 2.3
SoundSilent
Sharpest1080p
Length6 or 10 s, 6 s at 1080p
Starts fromA first frame
How to prompt each one, with sample takes: the Hailuo AI page.
No photo to start from? Make the first frame with MiniMax's image model, then hand it to a MiniMax video model. The clip keeps the frame's shape and adds its own sound.
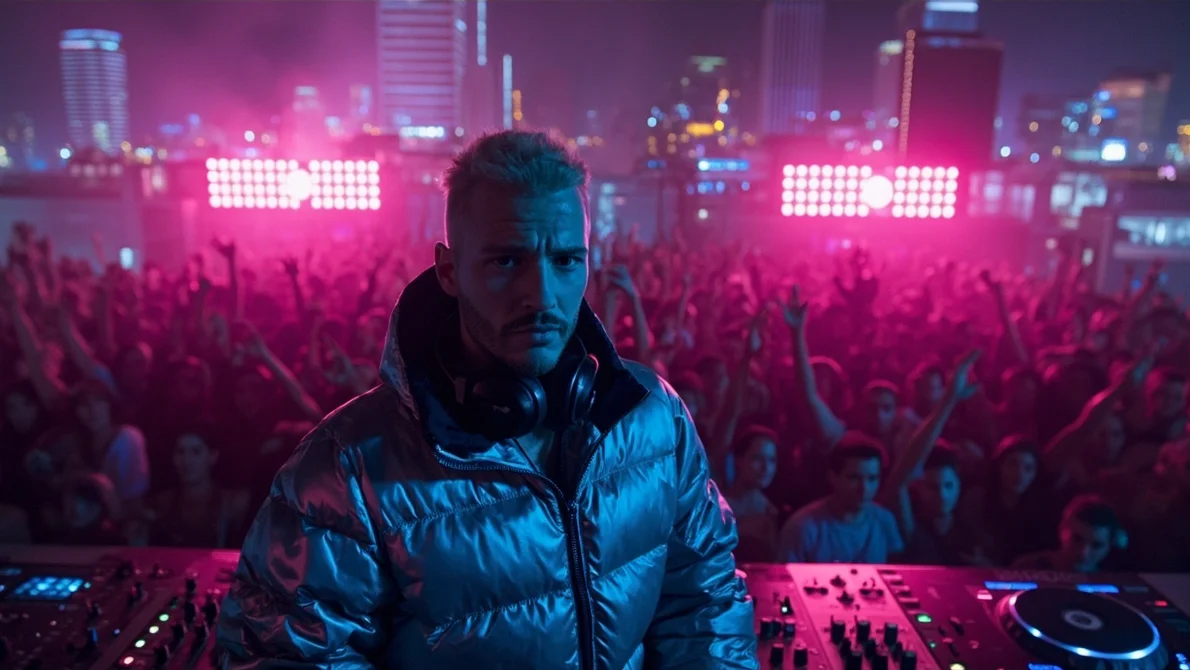
The prompt
Night rooftop party above a dense city skyline. A DJ in his twenties with a bleached buzz cut and a silver puffer jacket, headphones around his neck, stands at his decks facing the camera, framed from the waist up, the edge of the booth just in the bottom of the frame. Hard magenta and cyan light on his face. Behind him a packed crowd with raised hands, haze in the air, city lights out of focus. Full-frame color photograph, eye level.
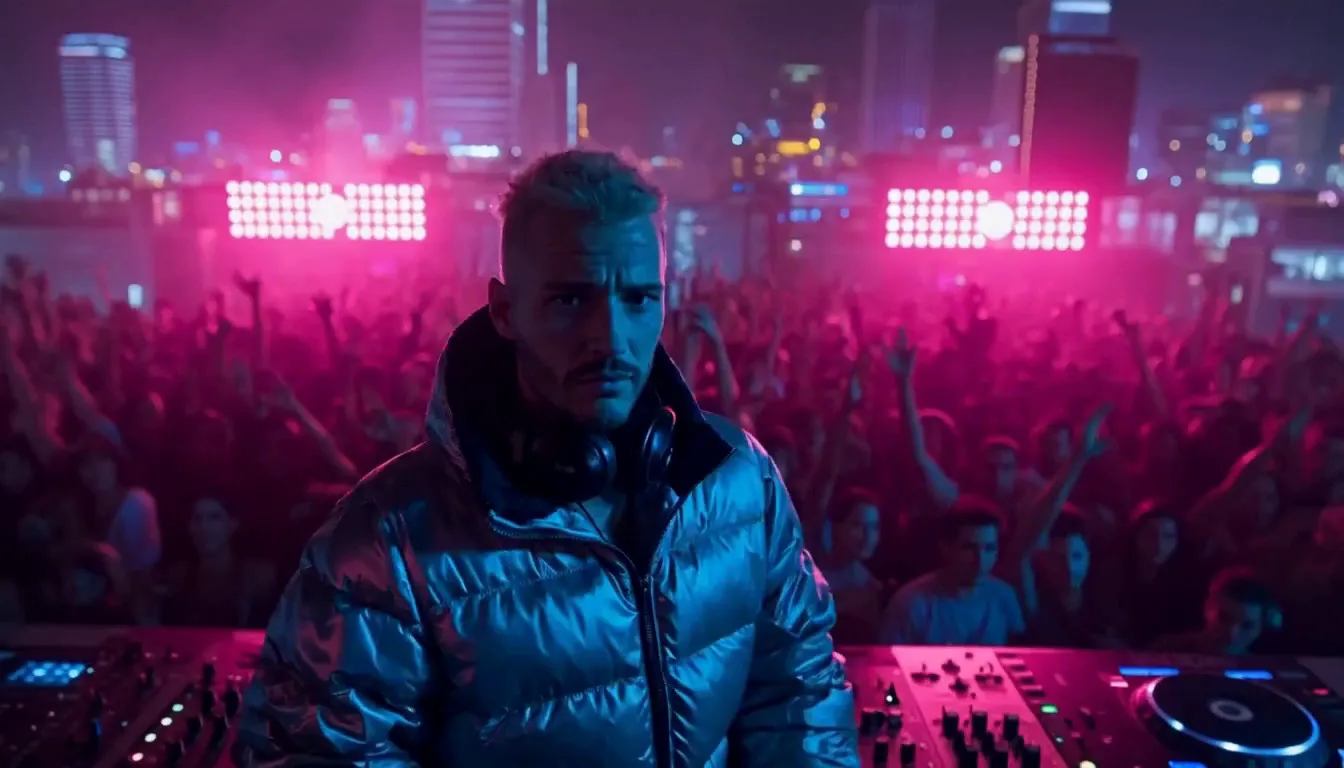
The prompt
integrated_multimodal_description:
[Shot 1] Live-action, cinematic. From the start frame: a DJ with a bleached buzz cut and a silver puffer jacket stands at his decks on a night rooftop, lit by hard magenta and cyan light, a packed crowd behind him. A pounding house track plays from the speakers and builds. He looks straight into the camera, grins and shouts over the music, then throws one hand up as the bass drops and the crowd behind him jumps. The camera pushes in fast, then shakes slightly on the drop. The DJ, hoarse and grinning, (S1) says: <d>[English] Last one. Make it loud!</d>
overall_soundscape:
The crowd screams and cheers as the bass hits. Feet stamp on the rooftop deck. Wind gusts across the roof.
non_diegetic_music:
N/A
MiniMax's text to speech model reads with the feeling you set. These are sample reads to listen to: one voice, one line, and only the emotion or the language changes. A new account can't run it, because it needs a MiniMax voice.
Sceneform offers no MiniMax preset voices, and voices you make here aren't MiniMax voices. Your own voice runs on Eleven v4, Qwen 3, or Seed Audio 1.0. See the AI voice generator.
“The results came in this morning. It's not what we expected. We start again on Monday.”
HappyEmotion happy
0:05AngryEmotion angry
0:06Mandarin普通话Language Chinese
0:06Cantonese粵語Language Cantonese
0:05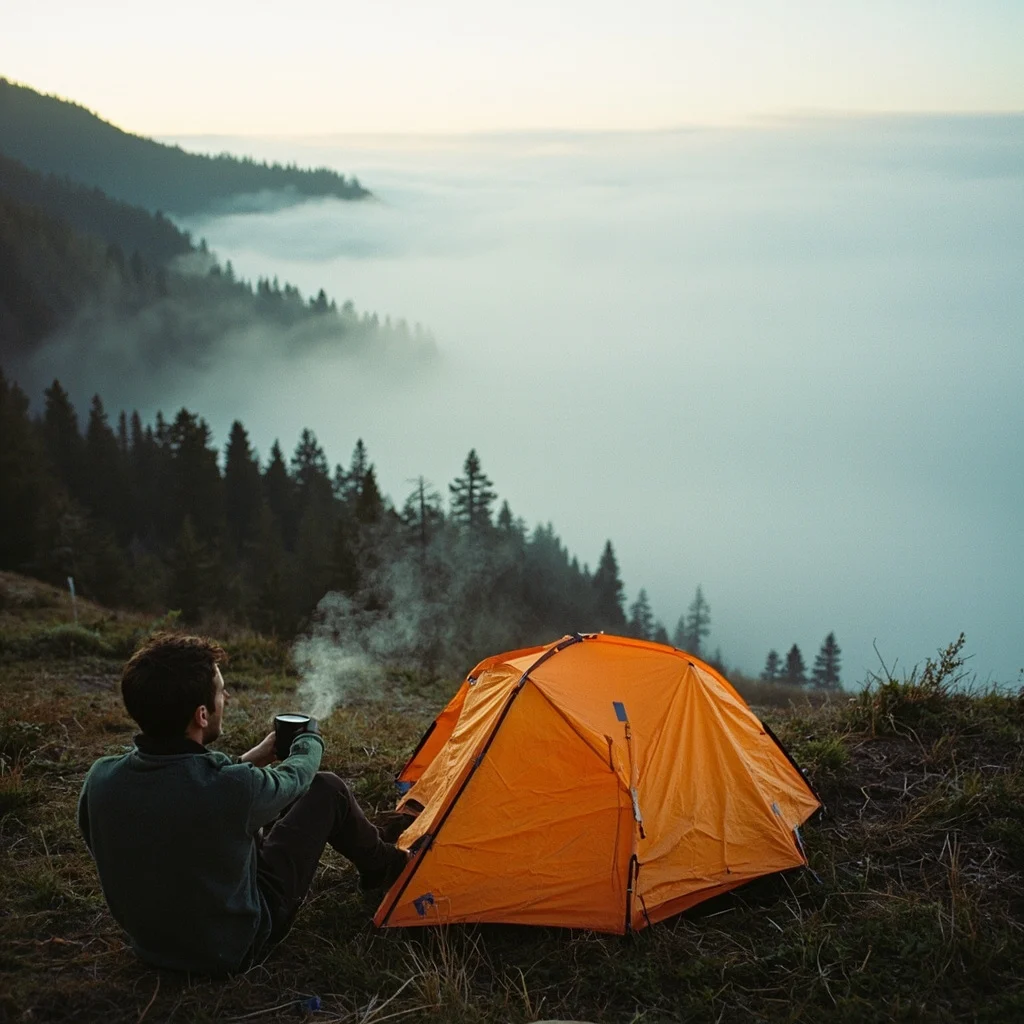
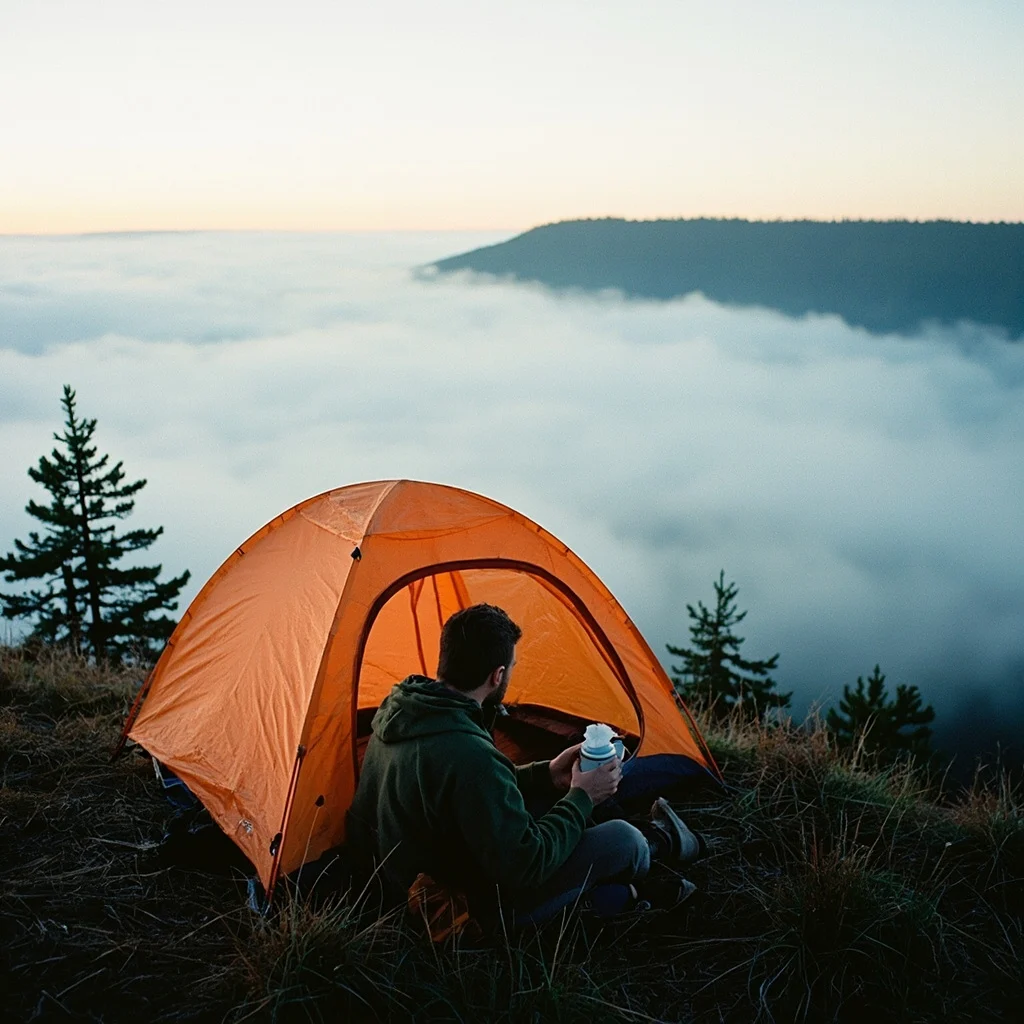
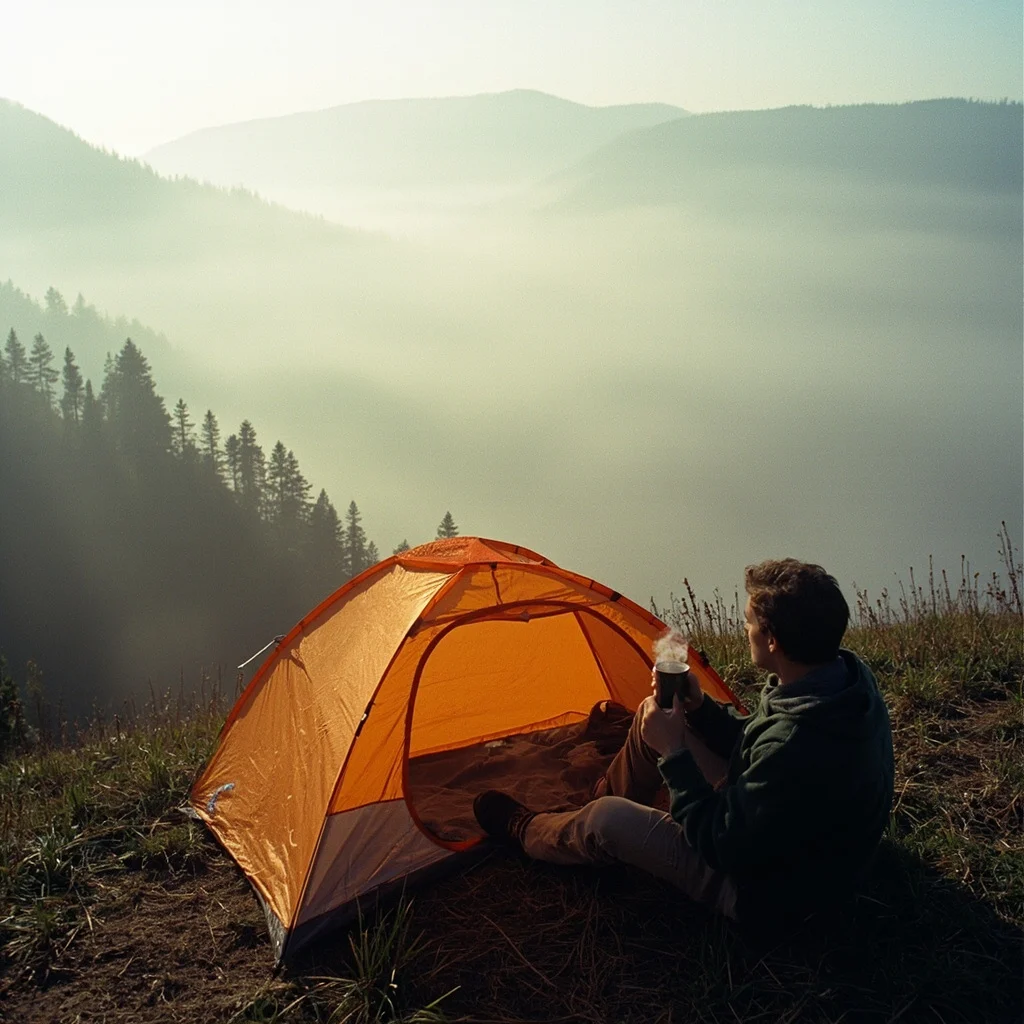
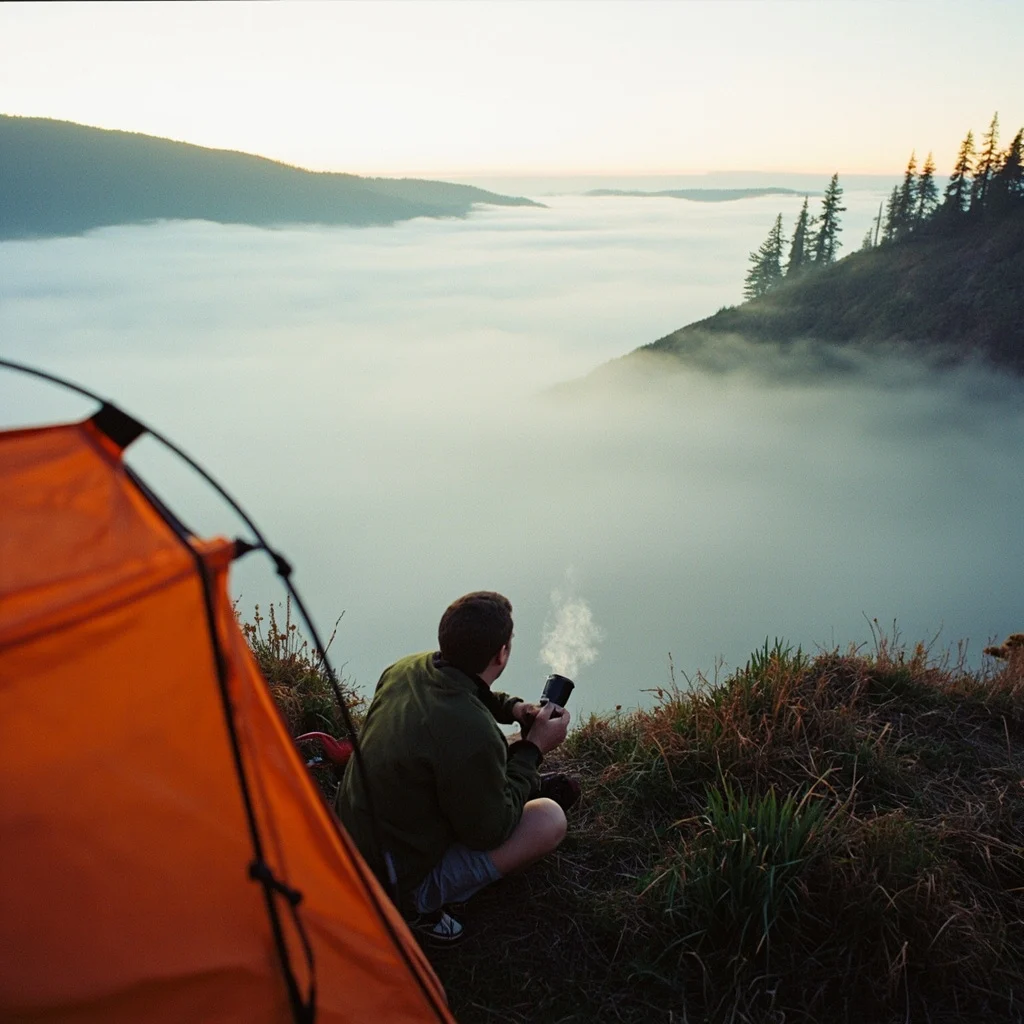
Image-01 is MiniMax's image model, made for quick, low-cost drafts. One run gives up to four takes on the same prompt, so you pick a direction before you spend more.
The prompt, one run
A small orange tent pitched on a grassy cliff edge above a valley filled with morning fog. A hiker in a green fleece sits outside the tent holding a steaming tin mug, seen from behind. Pine-covered hills fade into the mist. First light from the left, warm and low. Wide shot, film photograph.
Video for Hailuo and H3, or Image for Image-01.
The model picker lists every MiniMax model under its own name.
Describe the shot, the read, or the picture. Add a first frame or references when the model takes them.
Pick the plan for how much you post. Every model on every plan. Unused credits roll over. Cancel anytime.
Billed monthly
For solo creators posting every week
500 credits every month
Billed monthly
For creators posting daily across channels
1,300 credits every month
Billed monthly
For brands and production teams
2,700 credits every month
Billed monthly
For agencies running always-on content
5,500 credits every month
Want checkout, comparison tables, or a custom volume? See the full pricing page
MiniMax video and images, one plan.
Plans from $19 a month.